A weekly page for people who build with AI: mostly software, and the ads, video and sound that go out with it. If something doesn’t change what you’d use on Monday, it isn’t here.
The 30-second version
- The whole kit is a coding agent, two models, MCP, an instructions file and tests. If you have those, you are not behind.
- Three models launched. Claude Fable 5.2 is the new top model and 20% cheaper. Gemini 4 Carbon is close behind at under a third of the cost per task. Muse Ember matches Claude Haiku 5.5 at about a third.
- One habit to copy: review what your agent has written down.
- For video and images: Gemini Omni 1.2 Flash and OpenAI Images 2.6.
- From us: two apps in the stores, and the tools that built them.
Part one · The primer
The whole kit is five things
Almost everything announced in a given week is a new version of one of these. Get them in place once, and most news becomes a small upgrade you can take or leave.
- 01
A coding agent
A tool that reads your repo, runs commands and makes the change while you review. The big ones copy each other within weeks, so pick one, learn it properly, and stop comparing.
- 02
Two models: a daily driver and a cheap one
A strong model for thinking and a small, fast one for bulk work such as sorting and extracting. You rarely need the top shelf: Anthropic and Google both said so in this week’s launch posts.
Tier Anthropic OpenAI Google · Meta Top shelf Fable 5.2 GPT-6 Astra Gemini 4 Carbon Daily driver Opus 5.5 GPT-6.1 Sol Gemini 4 Argon Cheap and fast Haiku 5.5 GPT-6 Luna Muse Ember (Meta) - 03
MCP, the standard plug
The Model Context Protocol connects an agent to your database, issue tracker, docs and browser. Every major lab supports it, so it is safe to build on. Learn to add a server to your agent, and don’t write one-off integrations.
Start heremodelcontextprotocol.io
- 04
An instructions file
A plain text file in your repo that tells the agent how the project works: the commands, the conventions, what not to touch. It is the cheapest quality gain there is. Skills are the same idea for repeatable tasks.
FormatsAGENTS.mdAgent Skills
- 05
Tests, and a small eval set
An agent is as trustworthy as the checks around it. For code, that is your test suite. For a feature with a model inside, keep about 20 real examples with known good answers and rerun them when you change a prompt or a model.
Leave these until a real problem asks for them
Agent frameworksFine-tuningVector databasesPrompt coursesLeaderboard arguments
Part two · The week, 4 to 11 November
Three launches in two days
Anthropic, Meta and Google each shipped a model on 9 and 10 November. Here is where everything stands, on one independent scale.
Where the models stand today
Intelligence Index score, higher is better. The right-hand column is what one benchmark task cost to run.
New this weekAlready out
| Model | Score | Cost / task |
|---|---|---|
| Claude Fable 5.2New | 65 | $26.54 |
| Gemini 4 CarbonNew | 60 | $7.76 |
| Claude Opus 5.5 | 59 | $10.04 |
| GPT-6 Astra | 57 | $6.24 |
| GPT-6.1 Sol | 55 | $1.27 |
| Claude Sonnet 5.5 | 55 | $10.02 |
| GPT-6.1 Terra | 51 | $0.96 |
| Gemini 4 Argon | 50 | $9.95 |
| Claude Haiku 5.5 | 36 | $0.41 |
| Muse EmberNew | 36 | $0.14 |
| GPT-6 Luna | 28 | $0.15 |
New model · 9 Nov · Anthropic
Upgrade if you’re on Fable 5.1
Claude Fable 5.2 takes the top spot, at a lower price
- Index score, first place
- 65
- Per million tokens in and out. Was $10 / $50
- $8 / $40
- Faster output than Fable 5.1, at most
- 30%
Anthropic’s own advice is to start with Opus 5.5 and move up to Fable only for the most ambitious, open-ended work.
What to doOn Fable 5.1? Change the model ID to claude-fable-5-2, and read the release notes first if you call computer use over the API. Everyone else: nothing.
New model · 10 Nov · Google
Try on one hard task
Gemini 4 Carbon: nearly as strong, far cheaper to run
- Index score, second place
- 60
- Per million tokens until 30 Nov, then $4 / $20
- $2 / $10
- Per index task. Fable 5.2 cost $26.54
- $7.76
Google built Carbon for long, hard jobs and says Gemini 4 Argon is still the right pick for most engineering work.
What to doIf you have one task your current model keeps failing, try it on Carbon while it is half price. Otherwise stay where you are.
New model · 9 Nov · Meta
Test for bulk agent work
Muse Ember: a new floor for cheap agent work
- Index score, level with Claude Haiku 5.5
- 36
- Per million tokens in and out
- $0.10 / $0.50
- Per index task. Haiku 5.5 cost $0.41
- $0.14
Meta’s smallest model is made for the bulk work behind an agent: tool calls, routing, extraction. It finished the index tasks about five times faster than Haiku 5.5.
What to doIf a small model runs a simple, high-volume step for you, run Ember against your eval set.
Beyond code · Video, images, sound
Two releases for the things people see
If you make ads, product video or campaign images, these two change what you can do this week.
Video model · 5 Nov · Google
Try for ads and product video
Gemini Omni 1.2 Flash: 15-second video you edit by talking
- Longest clip, up from 10 seconds
- 15 s
- Per second at 720p, 30% lower than before
- $0.07
- What a 15-second 720p clip costs
- $1.05
You can now change a finished clip in conversation: swap the product or the background, change the light, switch the aspect ratio. Faces, packaging and brand colours hold from shot to shot.
What to doMaking ads or product video? Draft at 720p, edit by conversation, and upscale only the clip you keep. We used Omni Flash for the skies in our own film.
Image model · 4 Nov · OpenAI
Try for brand images
Images 2.6: GIFs, saved references and editing by markup
- Faster generation, by OpenAI’s count
- 50%
- Fastest image from the new Flare model
- 6 s
- New API models: Flare for speed, Sunburst for detail
- 2
In ChatGPT you can make short animated loops and save reference images of a person or product to reuse. In the API you can mark the exact area you want changed.
What to doIf you produce brand or campaign images, test markup editing on one real asset before your next campaign.
Also this week · Tools and heads-ups
Smaller things, quickly
Worth knowing about, without a story each.
Tools that shipped
- 5 NovCursor: Build Live AppsBuild a web app in Cursor and share it by link. Cursor sets up hosting, a database and sign-in, and runs security checks before anything goes live.Worth a look if you build internal tools.
- 2 NovClaude API: message threads (beta)The server keeps the conversation and you send only the new message. Long conversations start answering sooner. Your token bill stays the same.Worth turning on if your app holds long conversations.
- 5 NovElevenLabs: publish music to SoundCloudTracks made with ElevenLabs’ music model can now go straight to SoundCloud.Only matters if you release music.
Safe to skip
- Spotify’s new AI DJ voices. A feature for listeners. There is nothing in it to build with.
- Anthropic’s IPO roadshow. Business news. It doesn’t change your tools.
- GPT-6.2 rumours. OpenAI has announced nothing. Wait until it ships.
Practice · How to work
One habit worth copying
Tools change every week. How you work with them changes slowly.
Research · 6 Nov · Anthropic
Apply the idea
An agent’s notes go stale. Review them like code.
- Notes kept by the model that earned four badges in a game test
- 10 files
- Notes kept by the model that earned one
- 413 files
- Contract facts that survived a shared summary table. All 57 did with one page each
- 41 of 57
Anthropic studied what agents write down between sessions. The best kept a few notes about strategy and plans, and skipped what they could read off the screen. One saved a wrong fact and trusted it until a review pass fixed the note.
What to doOpen your instructions file and your agent’s saved notes this week. Delete what the agent can read from the code, keep the decisions and rules, and mark anything that is still a guess.
If you do one thing this week
Write down 20 real examples for the one AI feature you care about most.
Three models launched in two days, and it will happen again. With those examples saved, each launch is a ten-minute test with a clear answer.
Read the prompt
Help me build a small eval set for one AI feature.

Feature: [what it does, in one sentence]
Where the real inputs are: [logs, tickets, a folder, or I will paste some]

1. Collect 20 real inputs, including the awkward ones. Do not invent any.
2. For each one, write down what a good answer must contain and what it must never do.
3. Save them as one file in the repo, with a short script that runs all 20 against a model I name and prints pass or fail for each.
4. Run it once against the model I use today and show me the results.

Ask me before you guess at anything. Do not change the feature itself.
You can stop here. You’re caught up.
From our own bench
What we shipped, and what we used
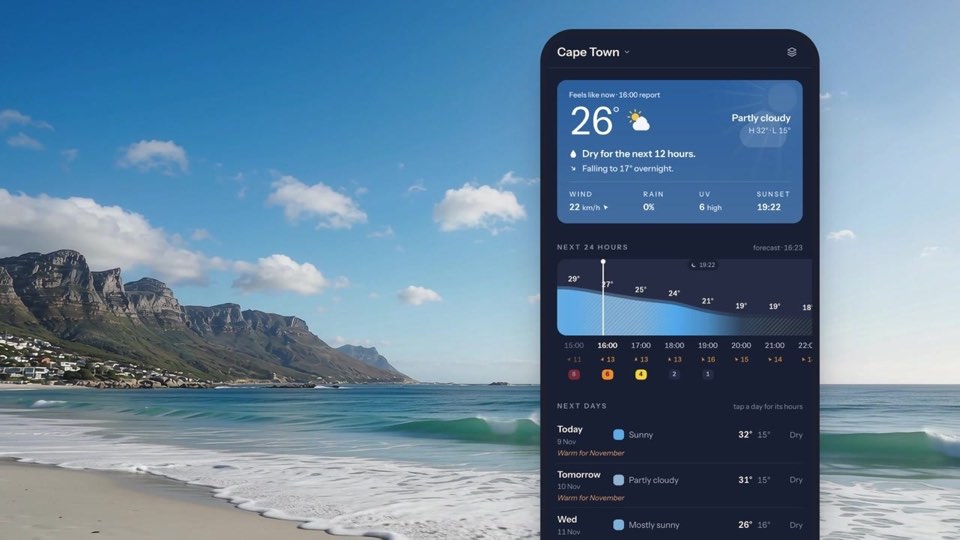
We build with the same kit. Two of our own apps reached the app stores this week.
Magic Weather
Live on Google Play on 9 November and on the App Store on 10 November. Hold your phone up to the sky and the app’s picture of it matches. No ads, no account.
Magic Sudoku
Version 1.0.2 is live on the App Store and Google Play as of 11 November. Sudoku with variant rules, community puzzles and leaderboards.
The tools behind them
| Job | What we used |
|---|---|
| Building | Claude Code, with an instructions file in every repo |
| Review | A second model, Codex on GPT-6 Astra, then GitHub Copilot, before a change merges |
| Apps | Expo and React Native: one codebase for iPhone, Android and the web |
| Film | Made from code, with no video editor: a web page that headless Chrome renders frame by frame. Skies by Gemini Omni Flash, voice and music by ElevenLabs |
The next one
Next Wednesday
Rather not give an email? Follow Bluebird on LinkedIn, where each issue is posted.